Shafeen Alam
Designing a governed, explainable AI assistant for threat & exposure management
Security analysts spent ~45 minutes per incident synthesizing exposure data across fragmented dashboards. I led the 01 design of Interpres's first AI assistant, which cut time-to-insight to 27 minutes and raised analyst trust from 62% to 81%.
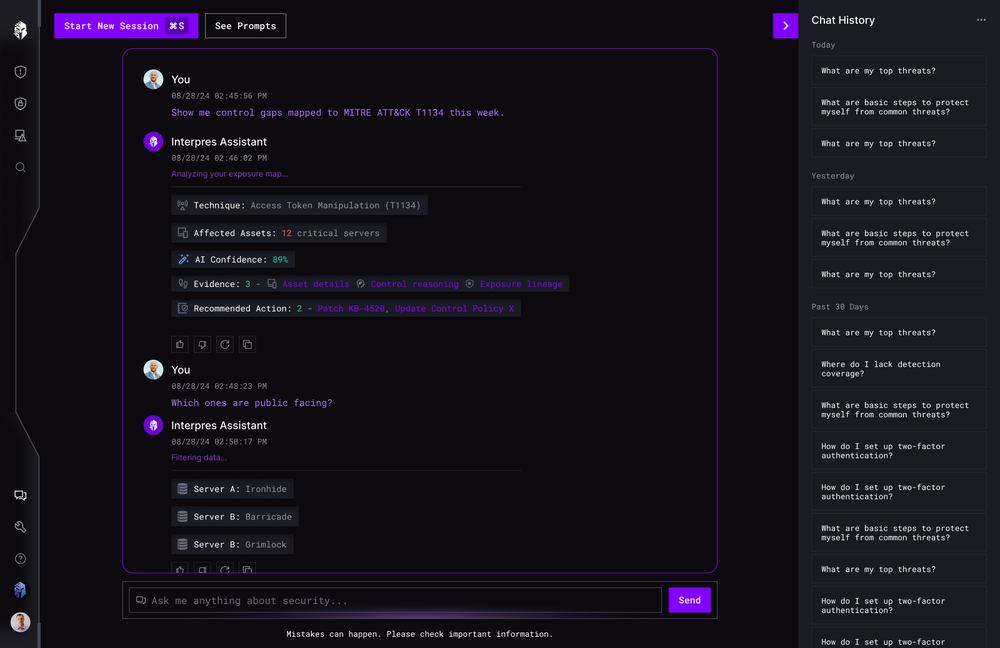
Every minute spent stitching dashboards together was a minute an exposure stayed unaddressed.
60-second read
Analysts spent about 45 minutes per incident synthesizing exposure data across fragmented dashboards.
Replace open-ended prose with a deterministic reasoning chain that is evidence-linked and confidence-scored.
Led the 0 to 1 design end to end: interaction model, evidence layer, safety and uncertainty states, design system.
Time to first insight 45 to 27 minutes. Analyst trust 62% to 81%.
01 · Shipped
A working 01 prototype, designed and validated in two weeks, that moved into Beta with real analysts, not a concept deck. It became the entry point to their workday, and a factor in closing new business.
02 · The problem
Security teams work across fragmented tools: alerts in one, exposure graphs in another, control coverage elsewhere. Even where the underlying data was rich, synthesis was entirely manual. Across 12 analyst interviews and 3 SOC manager sessions, the gap wasn't intelligence. It was structured, contextual reasoning.
“I don't trust automated suggestions unless I see the source.”
“Switching tools breaks my thinking.”
03 · What failed
First pass
Open-ended prose responses. In a security context that was unacceptable: hallucination risk, slow to scan under time pressure, and analysts finished reading unsure what to actually do next.
“Based on the available data, this could indicate a potential control gap related to access management, though further investigation may be needed to confirm the specific technique and assess the overall exposure level across affected systems...”
What replaced it
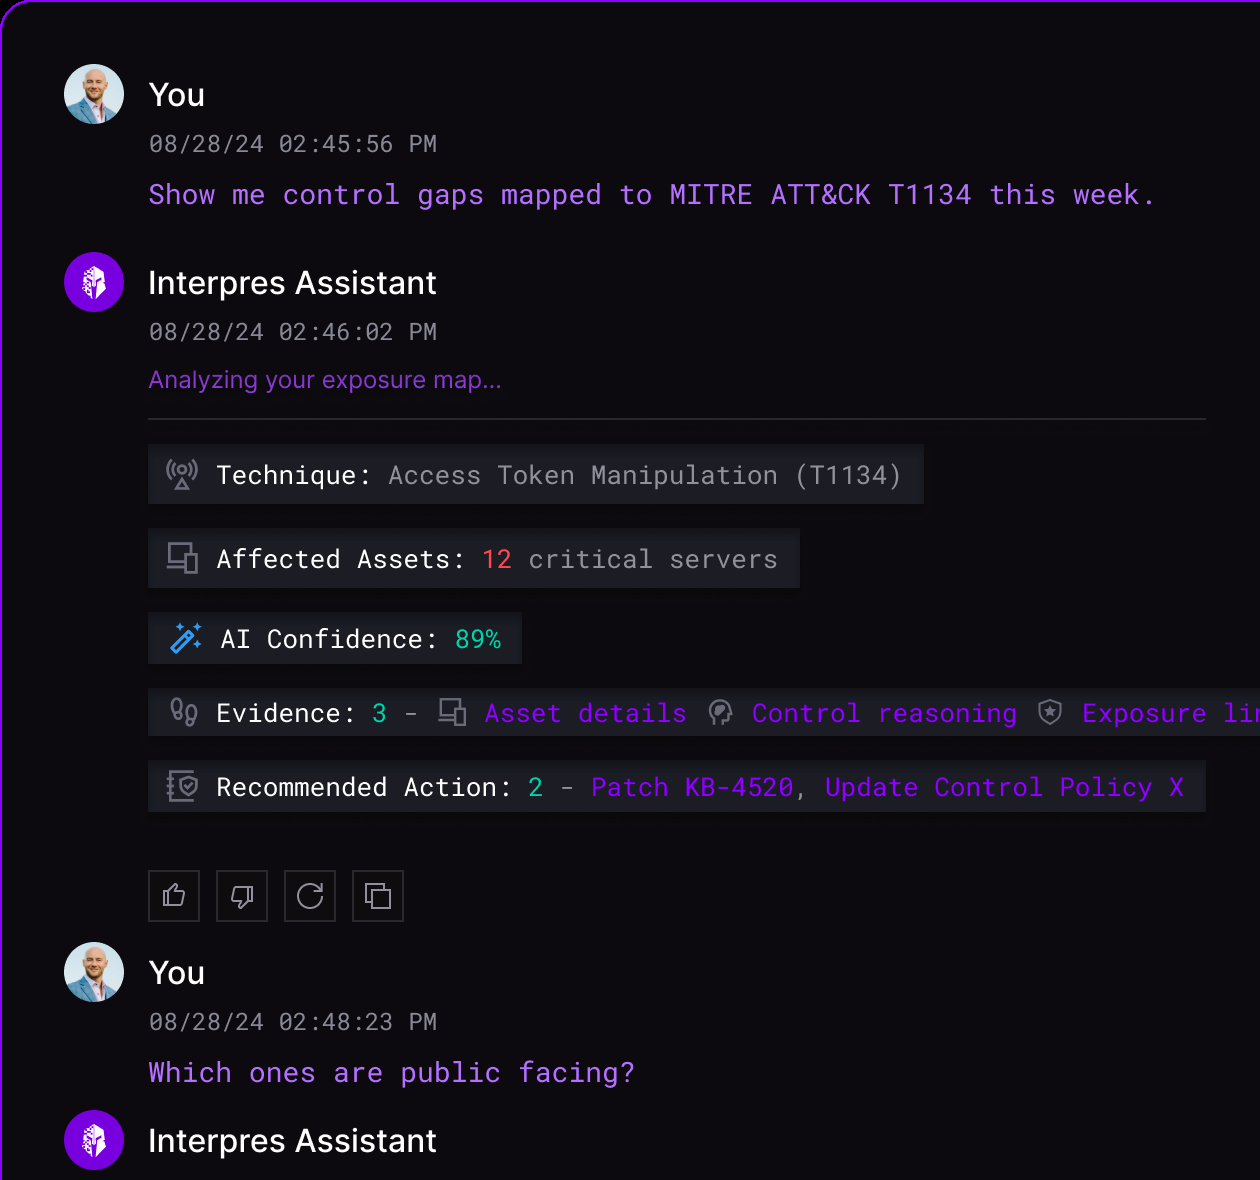
A deterministic reasoning structure, rendered as structured response cards instead of prose, with a “Why this matters” block on every answer.
04 · Where it lives
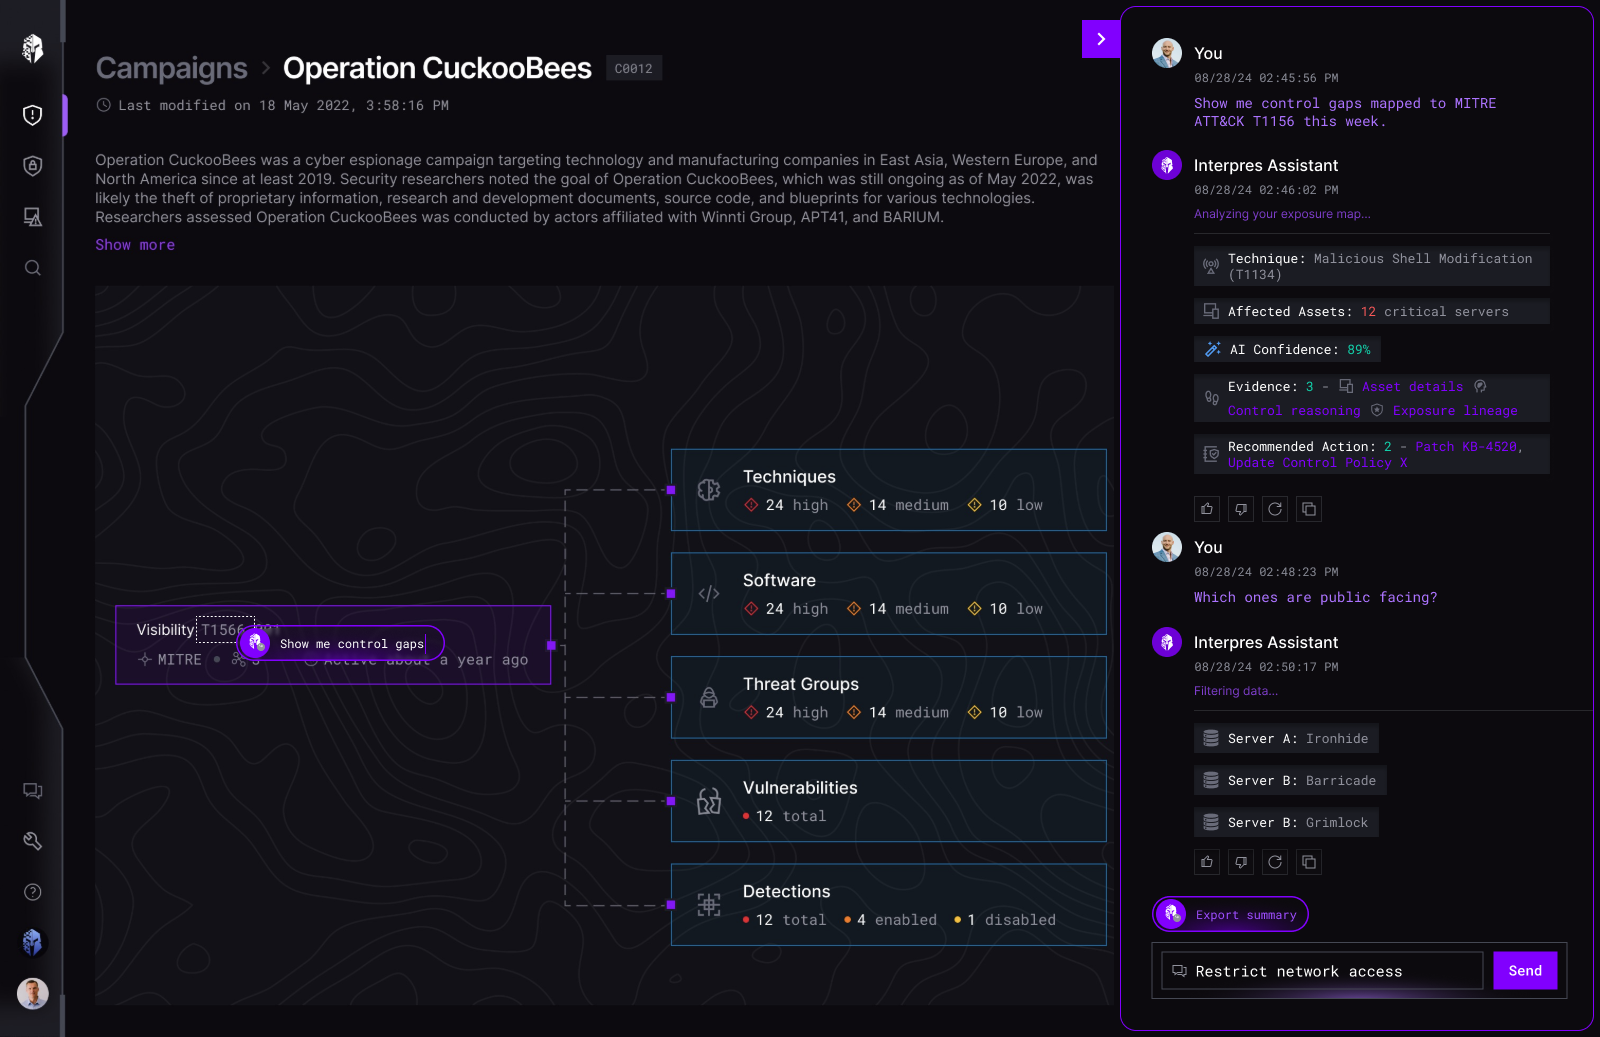
The assistant docks into the existing investigation rather than becoming a place you go.
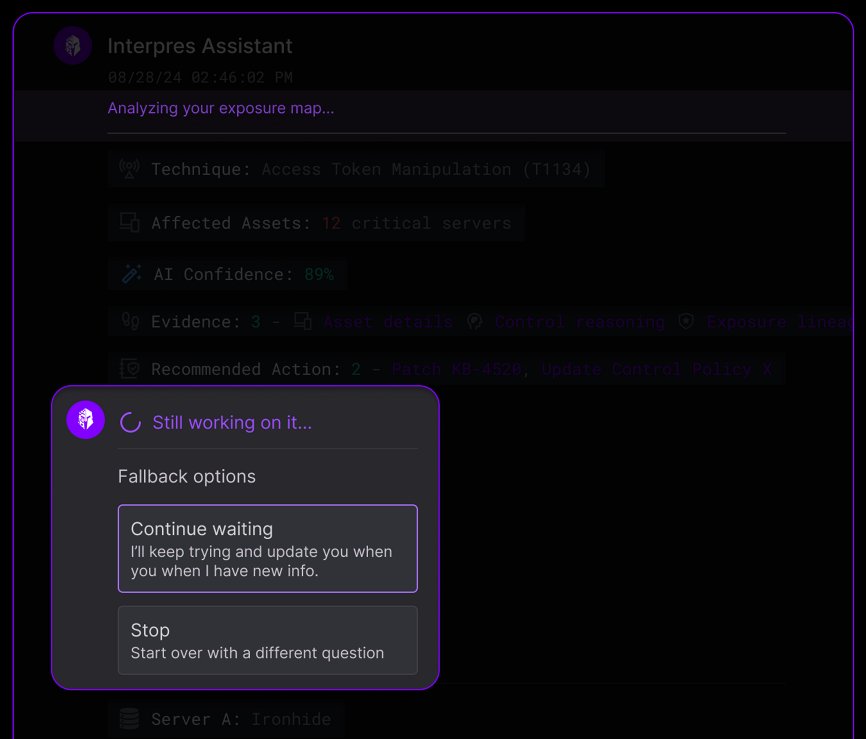
Exposure dashboards, asset details, and MITRE views stay visible while the assistant works with whatever is selected. The dock inherits the active exposure, asset, or technique, so a question never starts from nothing.
Evidence links return focus to the source view instead of opening a separate AI destination. That single decision is what keeps it an assistant rather than a second product.
The sequence it supports
It starts in place. The selected surface supplies the starting context for the question.
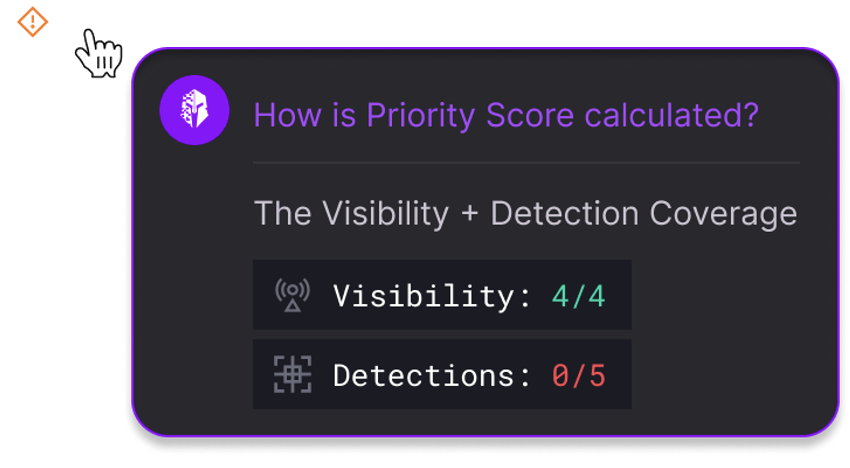
Clarify the score
Follow-up questions keep the current object and explain product language.
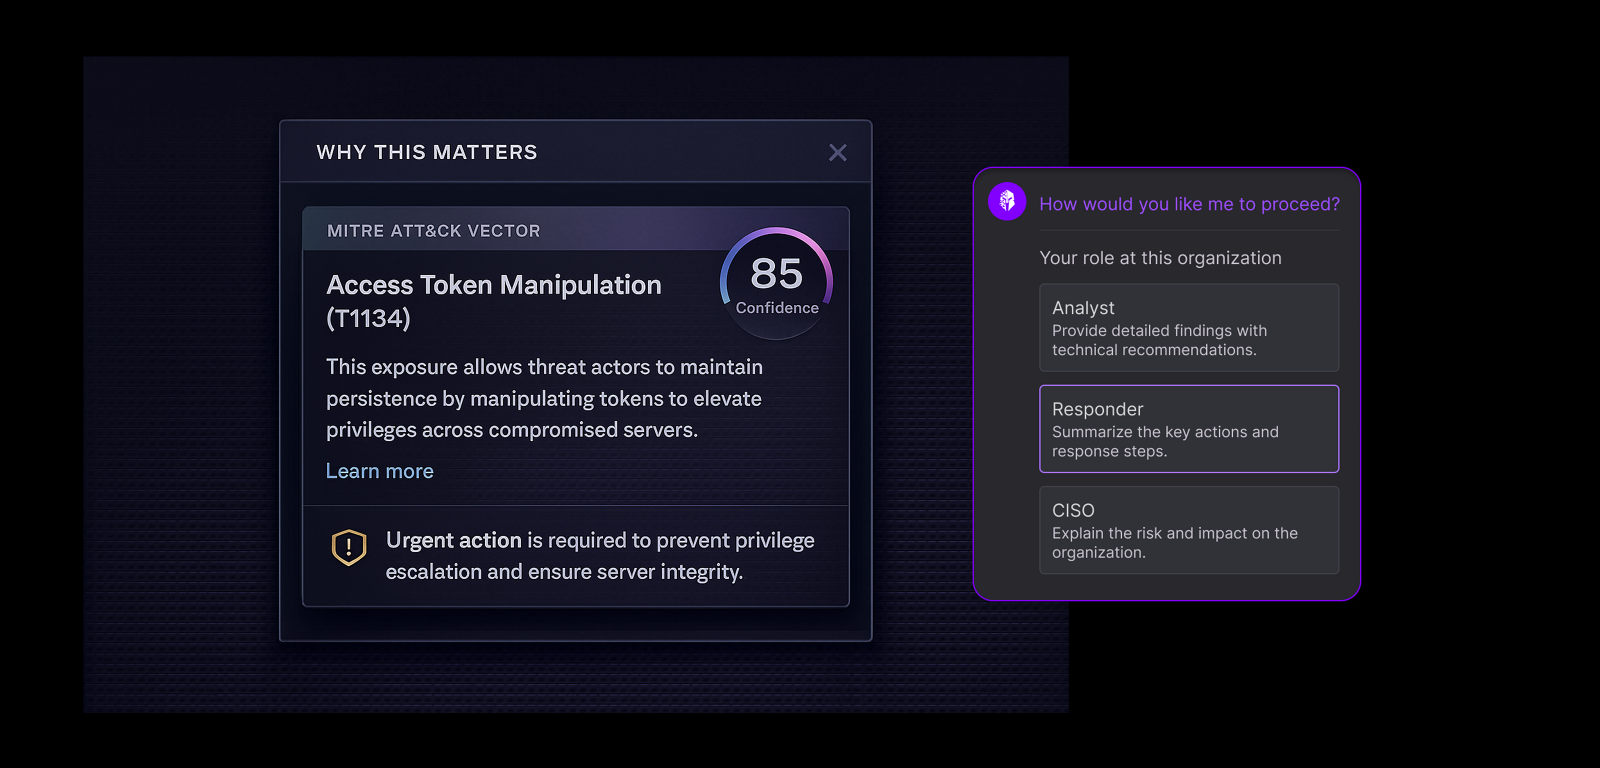
Inspect why it matters
Evidence and impact stay inspectable before the analyst chooses an action.
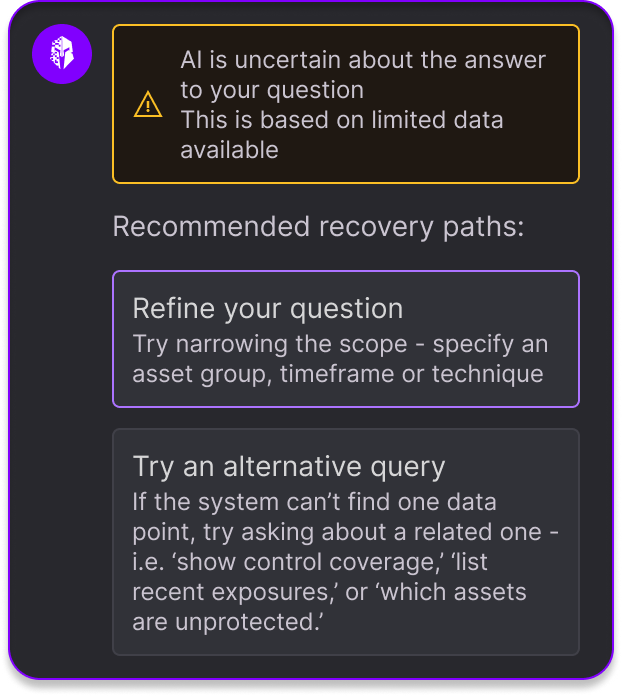
Recover safely
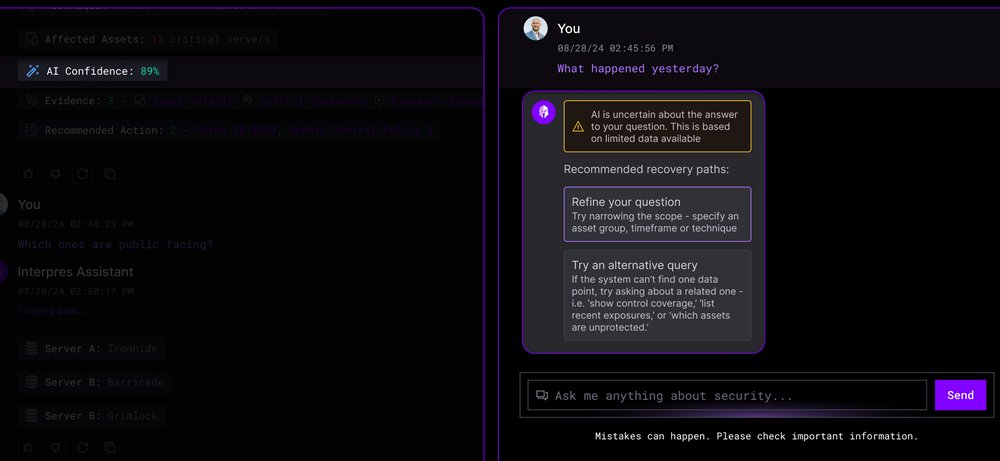
Low confidence offers refinement or an alternate query rather than guessing.
The patterns in place
05 · Live recreation
Not a screenshot. A working recreation of the reasoning structure and the evidence layer, with the two branches that matter most: uncertain and requires confirmation. Send the query, take either follow-up, then try the sensitive action below.

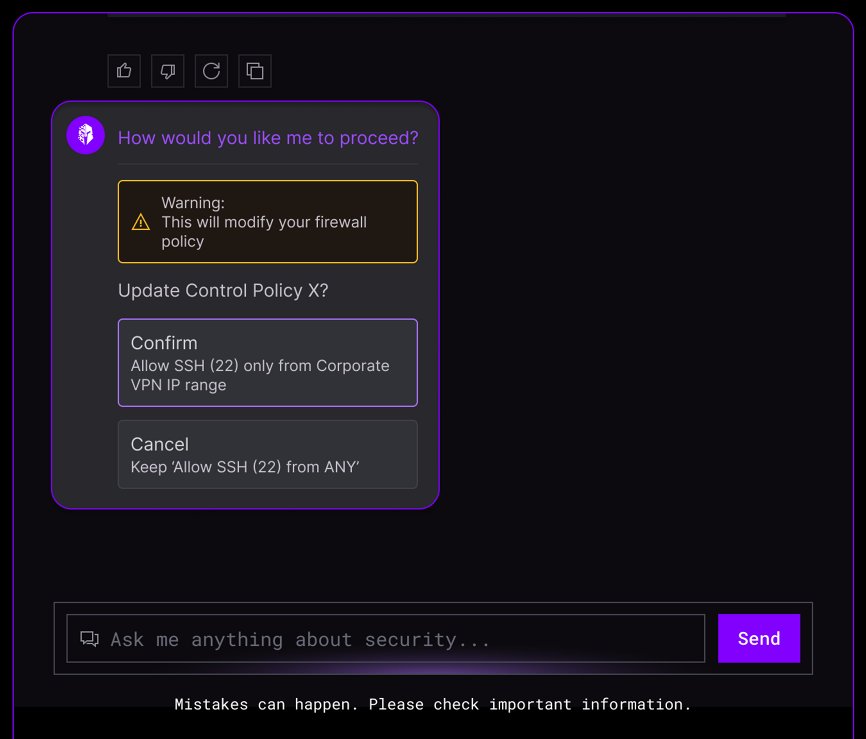
The second branch: a sensitive action
Every action that touches a live control stops here. One action, one confirmation, every time, and the dialog states the blast radius in the analyst's terms rather than the system's.
Try it. Confirm, or cancel and keep the existing rule.
06 · Confidence people
can use
A percentage helps only when someone knows what it means, can verify its basis, and understands the next action.
Precision without meaning creates false assurance, which in a security tool is worse than no number at all. So I treated the confidence score as three separate design problems rather than one label.
Score definition
A number is ambiguous until you say which thing it measures: model certainty, data quality, or the likelihood the recommendation is correct. Then explain its limits and the uncertainty that remains, in plain language.
Evidence and action
Reveal contributing signals, source lineage, freshness, and a short explanation. High confidence streamlines the path while keeping evidence available. Low confidence invites review, comparison, or escalation. Either way the analyst can correct, give feedback, or override.
Calibration and behavior
Across comparable cases, an 80% score should prove correct about eight times out of ten. So the thing worth instrumenting is behavior: acceptance and overrides, ignored scores, errors and recovery. Watch for blind acceptance and habitual dismissal, because both mean the number is not doing its job.
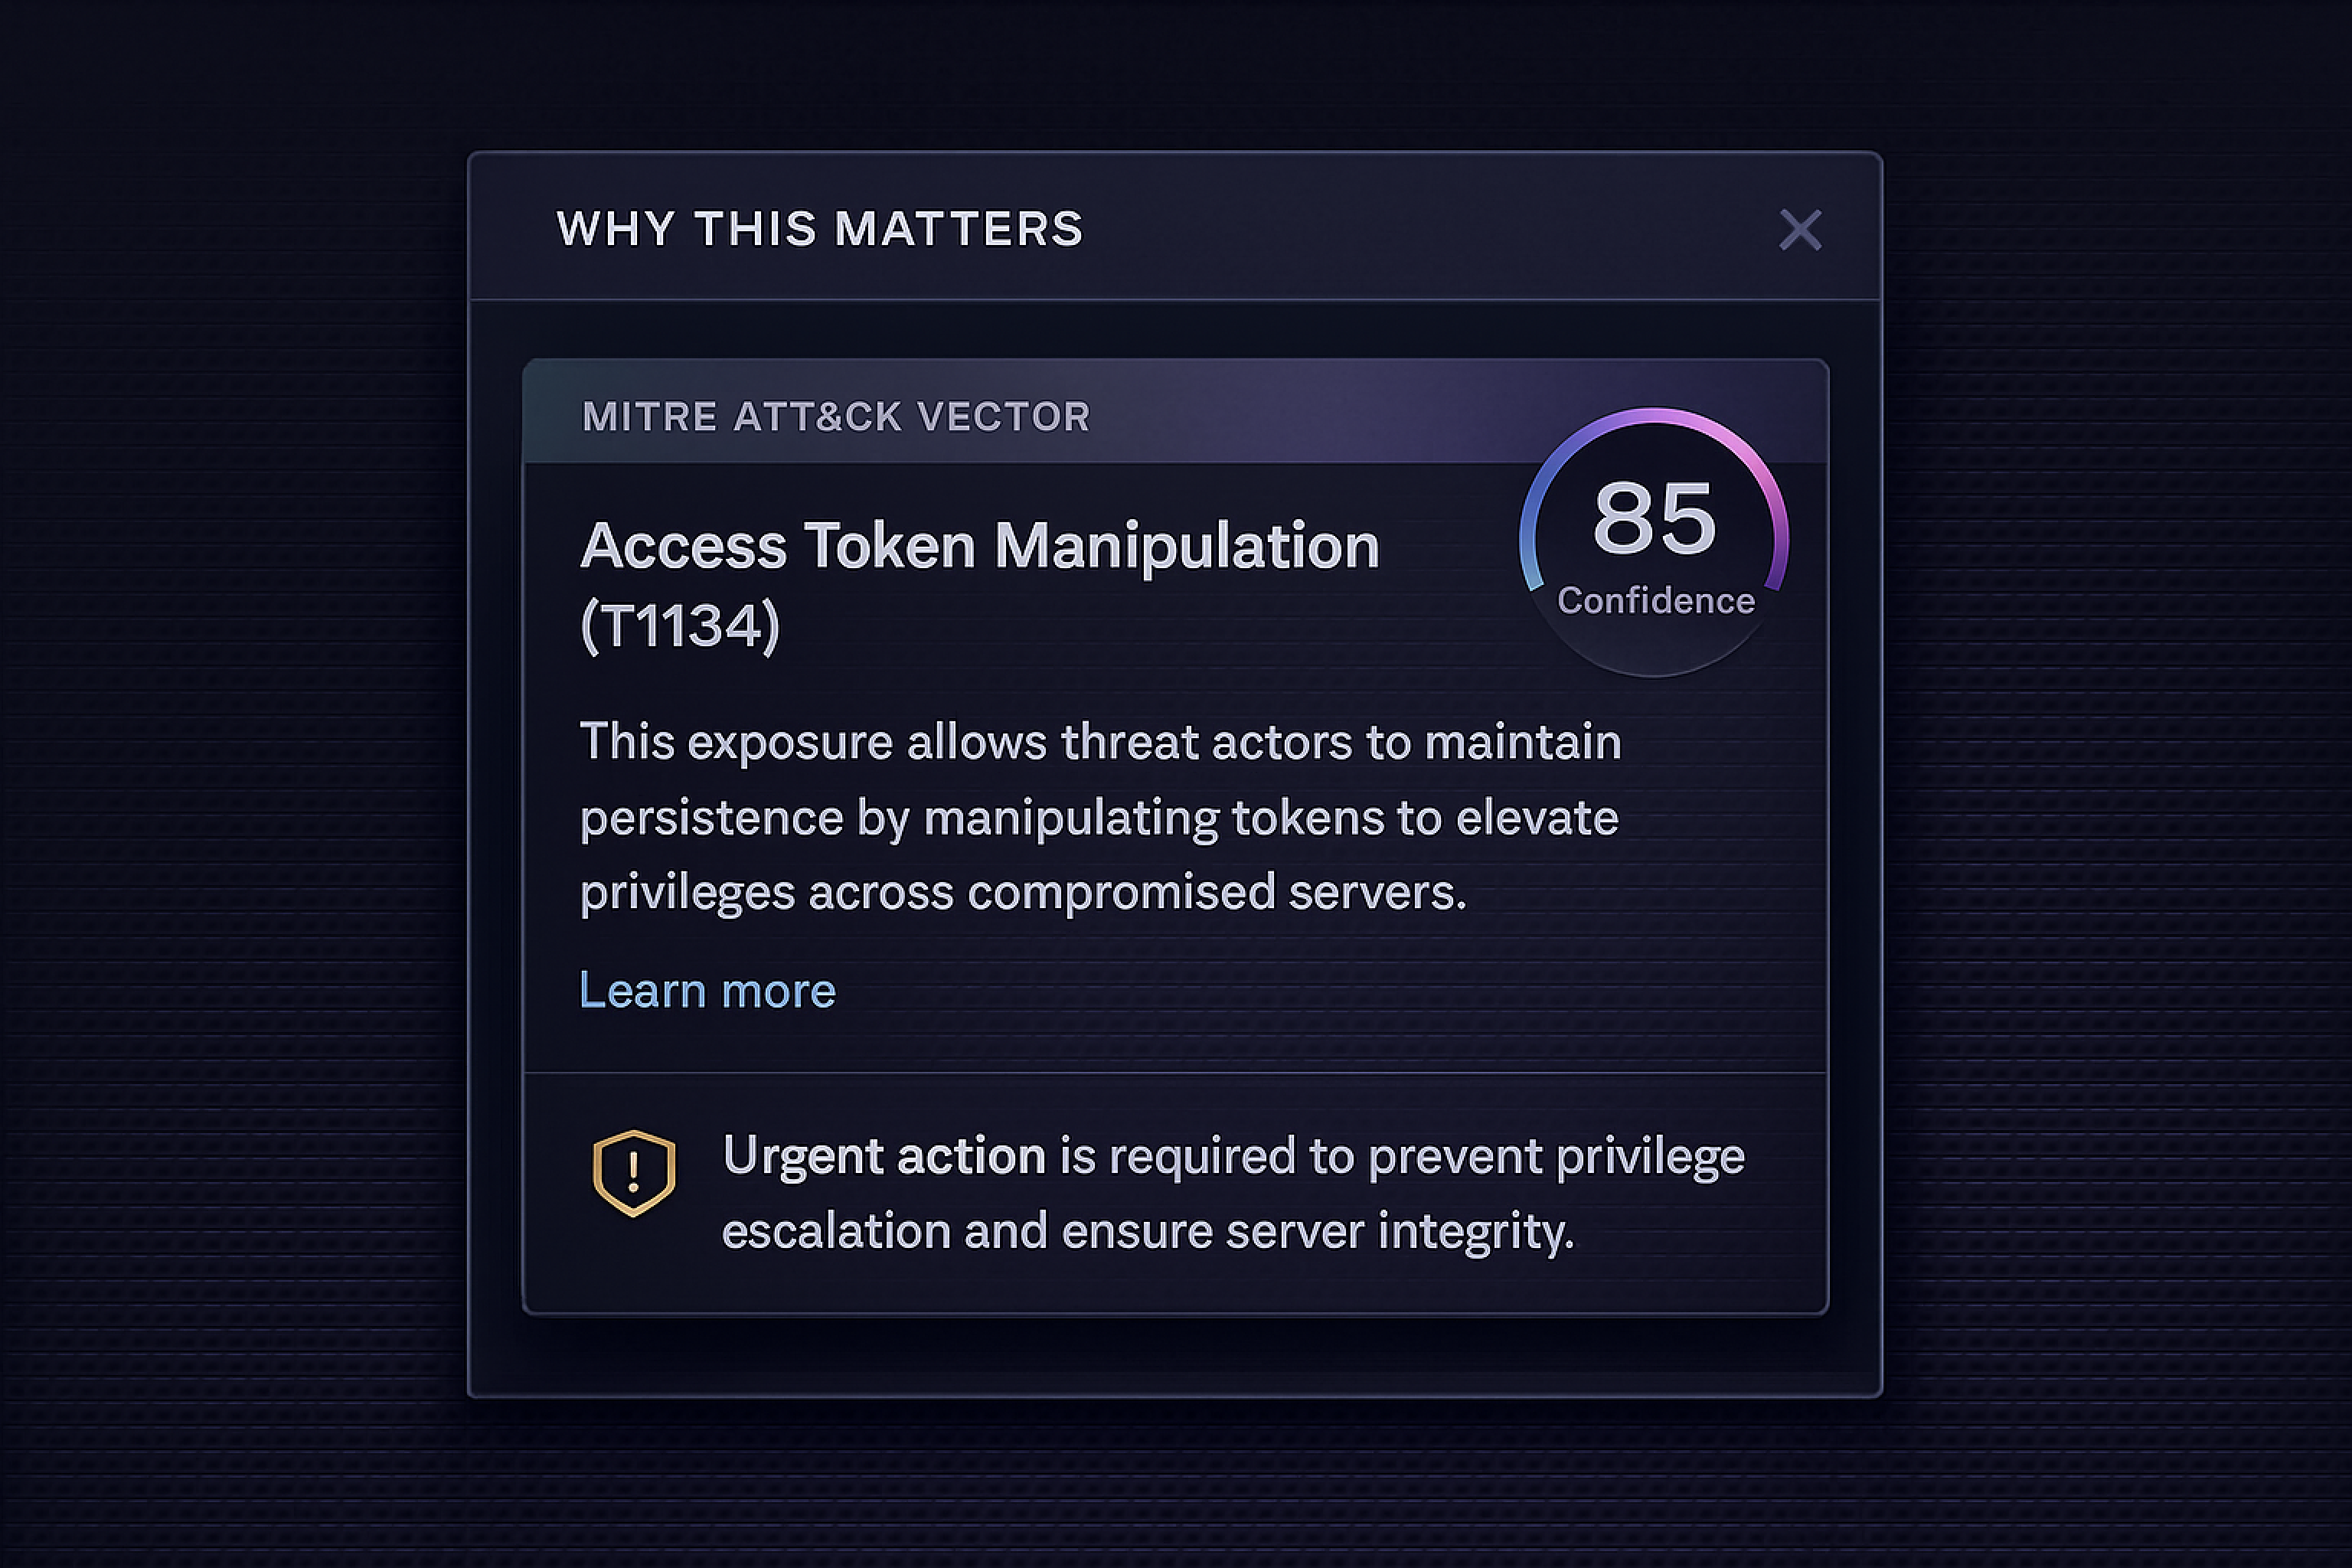
The confidence ring and the named technique in the sequence above are this framework in one panel: a score, the thing it measures, the evidence behind it, and the consequence if it is right.
An analyst who trusts the assistant exactly as much as it deserves is the target. Analyst trust rose from 62% to 81%, which is the number I would defend, because it moved without the accuracy claim changing.
07 · Built with engineering
A confidence score is not a design decision or an engineering decision. It is both, or it is a number nobody should trust.
The percentage had to combine measurable signals from the response pipeline and then map that uncertainty onto product behavior. Neither discipline could specify it alone, so we ran five stages with a design and an engineering track through each one.
Frame
Define what analysts need to judge
Identify measurable system signals
Instrument
Specify evidence and state requirements
Expose freshness, sources, and conflicts
Contract
Map confidence to interface behavior
Build the API and fallback logic
Validate
Test interpretation and recovery
Run calibration against reviewed cases
Monitor
Study acceptance and overrides
Track drift, latency, and failures
Decisions we made together
Four questions where a design answer without an engineering answer would have been fiction, and the reverse would have shipped a number with no meaning.
What the percentage represents
When the experience should slow down
Which actions always require confirmation
When calibration supports production use
The artifacts were joint too: a confidence definition, a state model, an API contract, an evaluation plan, and a monitoring dashboard.
The contract, in practice
Design defined the experience contract. Engineering confirmed what the system could return reliably. This is the shape we settled on.
Illustrative shape, written for discussion. It does not reproduce proprietary production code.
08 · What I cut
Multi-step autonomous execution. The assistant could have chained patch, policy update, and notify with no human between them. I scoped it to one action, one confirmation, every time, trading speed for trust, on purpose.
09 · Across the stack
I owned the interaction model end-to-end. Not a chat surface bolted onto dashboards, but how the AI reasons, grounds itself in evidence, and earns trust at each layer.
10 · Response
“Feels like a junior analyst who already knows our environment.”
Senior SOC Analyst
“For the first time, I can brief leadership using language they understand.”
CISO
Source: Mixpanel and OneStory analytics, measured during Beta.
In cybersecurity, ambiguity is risk. Design must reduce it.